AI floods science with ideas—but verification hits breaking point
The gist
AI is flooding science with ideas at record speed, but human verification can’t keep up—threatening to drown research in unproven, hallucinated findings.
What to know
- By 2026, AI-generated hypotheses exploded, with human experts like Donald Knuth now the critical bottleneck for validation and quality control.
- AI hallucinations—like 146,000+ fake citations and a 54% error rate in Grok 4.5—sparked industry-wide adoption of retrieval-augmented generation, layered audits, and new publisher restrictions.
- Publishers and institutions now demand human verification and transparency, but underinvestment in verification tools risks turning the AI discovery boom into a crisis of trust.
AI’s Idea Avalanche
AI has unleashed a flood of plausible scientific hypotheses, but the real bottleneck—and value—now lies in human-led verification and deep domain expertise.
By early 2026, AI had dramatically lowered the barriers to generating scientific hypotheses, enabling rapid exploration of countless candidate ideas much like Kepler’s iterative geometric experiments centuries ago. Terence Tao aptly compared Kepler to a 'high-temperature LLM,' highlighting how AI mimics this prolific proposer role by producing vast numbers of plausible scientific candidates, which has led to an explosion in paper volume but a decoupling of publication count from genuine discovery.
This surge in AI-generated hypotheses has shifted the core challenge in scientific research from idea generation to rigorous verification and validation. As Kepler painstakingly reconciled his theories with Tycho Brahe’s precise data, modern science faces a 'verifier problem' where expert human judgment and careful data analysis are indispensable to confirm AI-proposed findings. Knuth’s recent work validating a construction proposed by Claude but not proven by the AI itself underscores the irreplaceable role of human verifiers in closing the discovery loop.
Despite the critical importance of verification, institutional investment overwhelmingly favors improving AI proposers rather than building robust verifiers, creating a bottleneck in the scientific process. The traditional peer review system, designed for a slower pace of candidate generation, struggles to filter the flood of AI-produced papers, amplifying noise and making verification the scarce and most valuable skill. Experts emphasize that the future of impactful research lies with those who can pose incisive questions and develop strong verification methods grounded in deep domain expertise and epistemological clarity.
The human-AI discovery loop now centers on a division of labor where AI acts as the rapid proposer of hypotheses, but the human verifier and curator ensure scientific rigor and validity. This interaction—not the AI alone—constitutes the locus of genuine discovery, challenging simplistic narratives that AI either replaces scientists or is merely a stochastic parrot. As analyses stress, the key institutional need is not more 'AI scientists' managing models but researchers skilled in managing the entire loop with particular focus on strengthening verification capabilities.

Battling AI Hallucinations
Industry-wide safeguards like retrieval-augmented generation and human-in-the-loop review have become essential to keep AI’s fabricated outputs in check and maintain trust.
AI hallucinations—confident yet factually incorrect outputs including fabricated citations—pose a profound threat to user and institutional trust, especially in high-stakes domains like legal, financial, and scientific fields. By early 2026, strategies such as retrieval-augmented generation (RAG) and mandatory source attribution became standard to ground AI responses in verifiable documents, while maintaining hallucination rates below 2% was recognized as a pragmatic threshold to preserve trust, acknowledging that zero hallucinations remain unattainable. This multifaceted approach, combining automated detection, human expert review, and metrics tracking, reflects an industry-wide commitment to balancing AI fluency with factual accuracy.
Human-in-the-loop oversight emerged as an indispensable safeguard against hallucinations, with experts like Jack Lydecker underscoring that simple validation steps—such as verifying citations—can prevent the propagation of fabricated references that have already compromised reports from firms like KPMG and PwC. Without such human intervention, users tend to distrust AI outputs, leading to redundant work that erodes productivity gains and ROI. This consensus highlights that while AI’s probabilistic nature cannot eliminate hallucinations, integrating symbolic and rule-based systems alongside human judgment is essential to build and sustain trust.
The evolving design of AI models, which increasingly prioritize providing answers over admitting uncertainty, has paradoxically raised hallucination rates—as seen with Grok 4.5’s 54% hallucination rate compared to its predecessor’s 25%. This shift, driven by training incentives rewarding confident guesses, amplifies risks especially when AI-generated content mimics human conversational style, seducing users into unwarranted trust. Experts therefore advocate for encouraging AI to express uncertainty, promoting user skepticism, and demanding independent verification of detailed claims and citations to counteract this inherent limitation.
The infiltration of AI hallucinations into scientific literature, with over 146,000 fabricated citations detected in 2025 alone and more than 10,000 paper retractions in 2023, starkly reveals the insufficiency of current peer review and editorial processes to catch AI-generated falsehoods. Publishers like Elsevier and Springer Nature now mandate human verification of AI-generated references and restrict AI’s role to non-authorship tasks, emphasizing transparency and accountability. This crisis in scholarly trust underscores the urgent need for robust human-in-the-loop frameworks and transparent AI governance to safeguard the integrity of research outputs.

Verification Becomes King
Code-first reproducibility, multi-layered audits, and real-time citation checks have redefined scientific rigor, making robust verification the new gold standard in research.
By mid-2026, a paradigm shift in scientific verification emerged with the adoption of rigorous code-first methodologies, where no quantitative claim was accepted without executable code subjected to deliberate attempts at falsification. This approach, exemplified by practices that publicly document errors and corrections—such as benchmarks off by orders of magnitude and retracted theorems—redefined verification as the scarce, valuable asset in knowledge production, fundamentally reorganizing research industries to prioritize reproducibility and robustness over mere idea generation.
Ensuring the accuracy of AI-generated research outputs necessitates a multi-layered verification framework that combines machine audits with human oversight. Analysis from July 2026 revealed that even advanced AI tools like Perplexity Computer produced substantive errors, underscoring the critical need to audit AI outputs using a different, ideally stronger, model to avoid shared blind spots. This dual approach—machine audits to catch overlooked errors followed by human review for nuanced judgment—along with transparent correction disclosures, forms the backbone of trustworthy AI-assisted research.
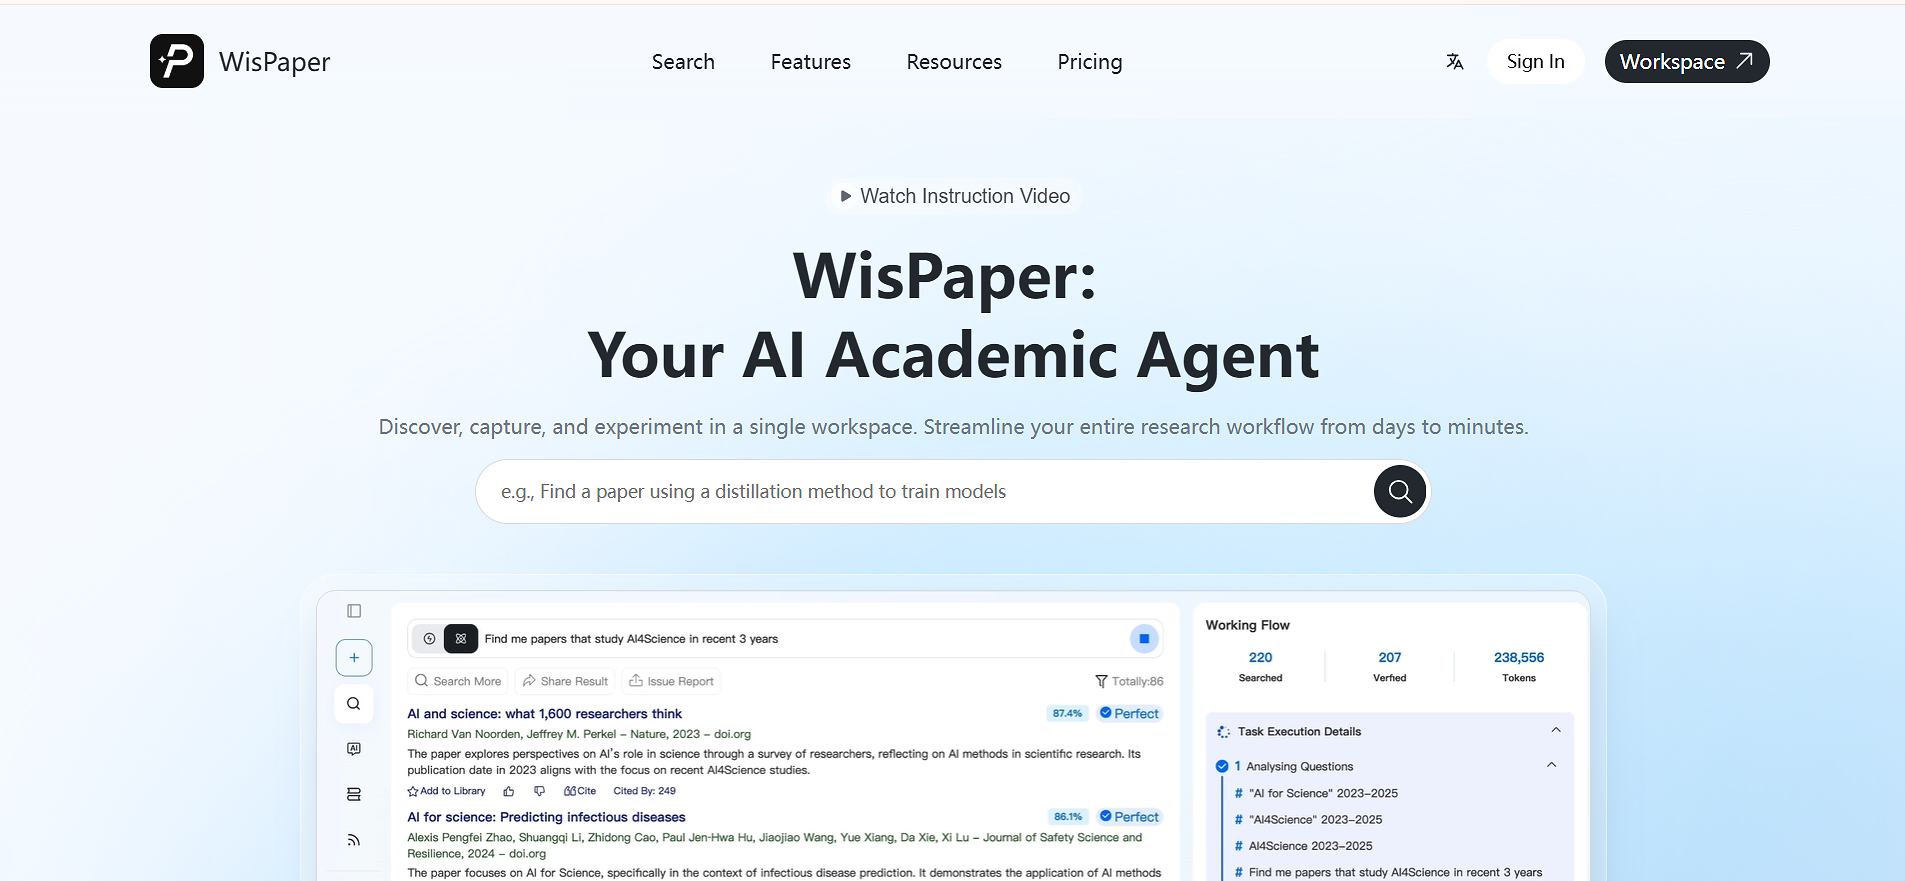
Innovations like Wispaper’s True Cite and Google’s ScientistOne have set new benchmarks in citation and evidence verification to combat AI-induced misinformation in academic research. Launched in August 2026, True Cite integrates seamlessly into Wispaper’s AI Research Agent to verify references against authentic publications, addressing widespread issues of fabricated citations and invalid DOIs. Meanwhile, ScientistOne’s Chain-of-Evidence architecture achieved zero hallucinated citations across 75 papers by combining real-time literature retrieval, transparent audit trails, and multi-step verification, elevating reproducibility to state-of-the-art levels on rigorous benchmarks like MLE-Bench and Parameter-Golf.

Institutions Tighten the Reins
Publishers and organizations are enforcing strict human oversight, layered audits, and transparency protocols to prevent AI-generated errors from undermining credibility.
Institutional and professional entities across sectors have recognized that unchecked AI-generated content poses significant risks to credibility and reputation, as evidenced by high-profile incidents at KPMG and PwC where AI hallucinations led to fabricated citations and erroneous data. These failures underscore the critical need for robust human oversight and validation protocols, with leaders like Jack Lydecker of Gainsight emphasizing the importance of establishing clear guardrails and human-in-the-loop mechanisms to ensure AI processes the right data and outputs verifiable information.
Scientific publishers such as Springer Nature and Elsevier have adapted their policies to allow AI use only for limited tasks like proofreading and translation, explicitly rejecting AI authorship to maintain accountability for research integrity. Leading journals including Nature and Science have issued warnings about AI 'hallucinations'—fabricated references and plausible yet false statements—that existing peer review systems cannot fully detect, a challenge exacerbated by a surge to over 3.1 million manuscript submissions that overwhelm traditional human reviewer capacity.
To combat AI-induced errors in research, publishers and researchers advocate a layered verification approach combining independent audits by different AI models with meticulous human review. This dual strategy leverages the strengths of machine audits to catch overlooked errors and human judgment to identify nuanced mistakes beyond algorithmic detection, while institutional protocols now reject research generated solely within the AI system to prevent unverified outputs from entering the scientific record. Transparency is also paramount, with explicit disclosure of AI-generated errors and corrections becoming a standard to uphold trust.
The PwC scandal has catalyzed a broader industry shift toward enhanced AI governance frameworks within professional services, emphasizing provenance tracking, audit trails, and mandatory human validation of all AI-generated citations. Recognizing that generative models produce citation-like text based on stylistic patterns rather than actual source retrieval, firms are now instituting systematic citation verification workflows to prevent reputational damage and ensure the integrity of AI-assisted outputs.
Human-AI Discovery Loop
Human experts now drive research quality by curating and validating AI-suggested ideas, but chronic underinvestment in verification tools risks stalling scientific progress.
By mid-2026, the human-AI collaboration model in scientific discovery has crystallized into a dynamic interaction loop where AI systems act as rapid proposers of candidate solutions, while human experts retain ownership of research questions and serve as indispensable verifiers and curators. Donald Knuth’s meticulous validation of AI-suggested mathematical patterns exemplifies this synergy, underscoring that the causal power lies not solely in AI or humans but in their iterative interaction. However, this evolving paradigm exposes a critical institutional imbalance: while vast investments pour into enhancing AI proposers—larger models and faster generation—verification tools and processes remain underfunded and cumbersome, creating a bottleneck that threatens the reliability of scientific outputs.
The traditional academic infrastructure, including peer review systems, is increasingly ill-equipped to handle the AI era’s deluge of plausible hypotheses, where models can generate thousands of candidates in an afternoon. This flood demands new verification frameworks and a reframing of institutional roles from managing AI models to orchestrating the human-AI discovery loop. As Vivek Natarajan of Co-Scientist highlights, even a single hallucinated claim can invalidate entire outputs, emphasizing the necessity of deep human expertise and epistemic humility in AI collaborators—mirroring AlphaFold’s confidence reporting—to build trust and prevent 'confident nonsense at scale.'
Human-in-the-loop approaches are paramount for mitigating AI hallucinations and fostering trust, as the probabilistic nature of AI precludes complete error elimination. Without this trust, users often resort to redoing entire tasks, negating AI’s efficiency gains. Therefore, integrating human verification is not just a safeguard but a strategic imperative to realize return on investment and effective AI adoption in research workflows. This necessity calls for a rebalancing of funding priorities towards verification tools and change management strategies that embed human expertise at the core of AI-augmented scientific discovery.
A fundamental tension persists in AI-driven scientific discovery between fostering originality and ensuring reliability. AI agents tuned for caution risk producing safe but uninspired hypotheses, while those optimized for novelty may generate error-prone outputs. This delicate balance necessitates designing collaboration models that harness AI’s rapid ideation capabilities—such as Co-Scientist’s subagent architecture for hypothesis generation and critique—while anchoring outputs firmly in human validation to maintain scientific rigor and trustworthiness.
AI Assistants Reshape Research
AI tools like ChatGPT, Claude, and Perplexity deliver rapid, citation-rich research at a fraction of traditional cost, but require vigilant human oversight to ensure accuracy.
By mid-2026, AI assistants like ChatGPT and Vox demonstrated impressive reasoning skills and the ability to generate credible, citation-rich independent research rapidly, accurately summarizing nuanced quantitative data such as gradual dietary changes among respondents. These systems notably reduced hallucination risks by refusing to fabricate sources when asked for nonexistent insights, marking a significant advance in trustworthy AI-driven research outputs.
AI assistants have revolutionized research workflows by producing detailed, citation-rich reports within minutes—a task that traditionally required days or even months and substantial funding, as exemplified by a recent classification project completed in days for just $480 compared to past university-led efforts costing hundreds of thousands. However, maximizing this efficiency demands precise, detailed queries and user vigilance in spot-checking sources to mitigate inaccuracies and reliance on potentially weak publishers, underscoring the importance of informed human oversight.
Different AI models offer complementary strengths: Perplexity excels in delivering concise results rapidly, while ChatGPT and Claude provide exhaustive, in-depth analyses, with Claude scanning over 500 sites in under 20 minutes. This diversity allows researchers to tailor AI tools to their specific needs, balancing speed and depth to accelerate discovery without sacrificing thoroughness.
AI agents are transforming scientific research by automating routine tasks such as literature reviews, data curation, and code generation, enabling scientists—even those without programming expertise—to generate functional scripts from natural language commands swiftly. Despite these gains in ideation and workflow acceleration, challenges remain in validation and error management; as Vivek Natarajan warns, a single hallucinated claim can undermine entire outputs, highlighting the critical need for AI models to develop epistemic humility and transparent uncertainty communication to build trust and ensure reliable scientific collaboration.