Million-hour video training propels robots past old limits
The gist
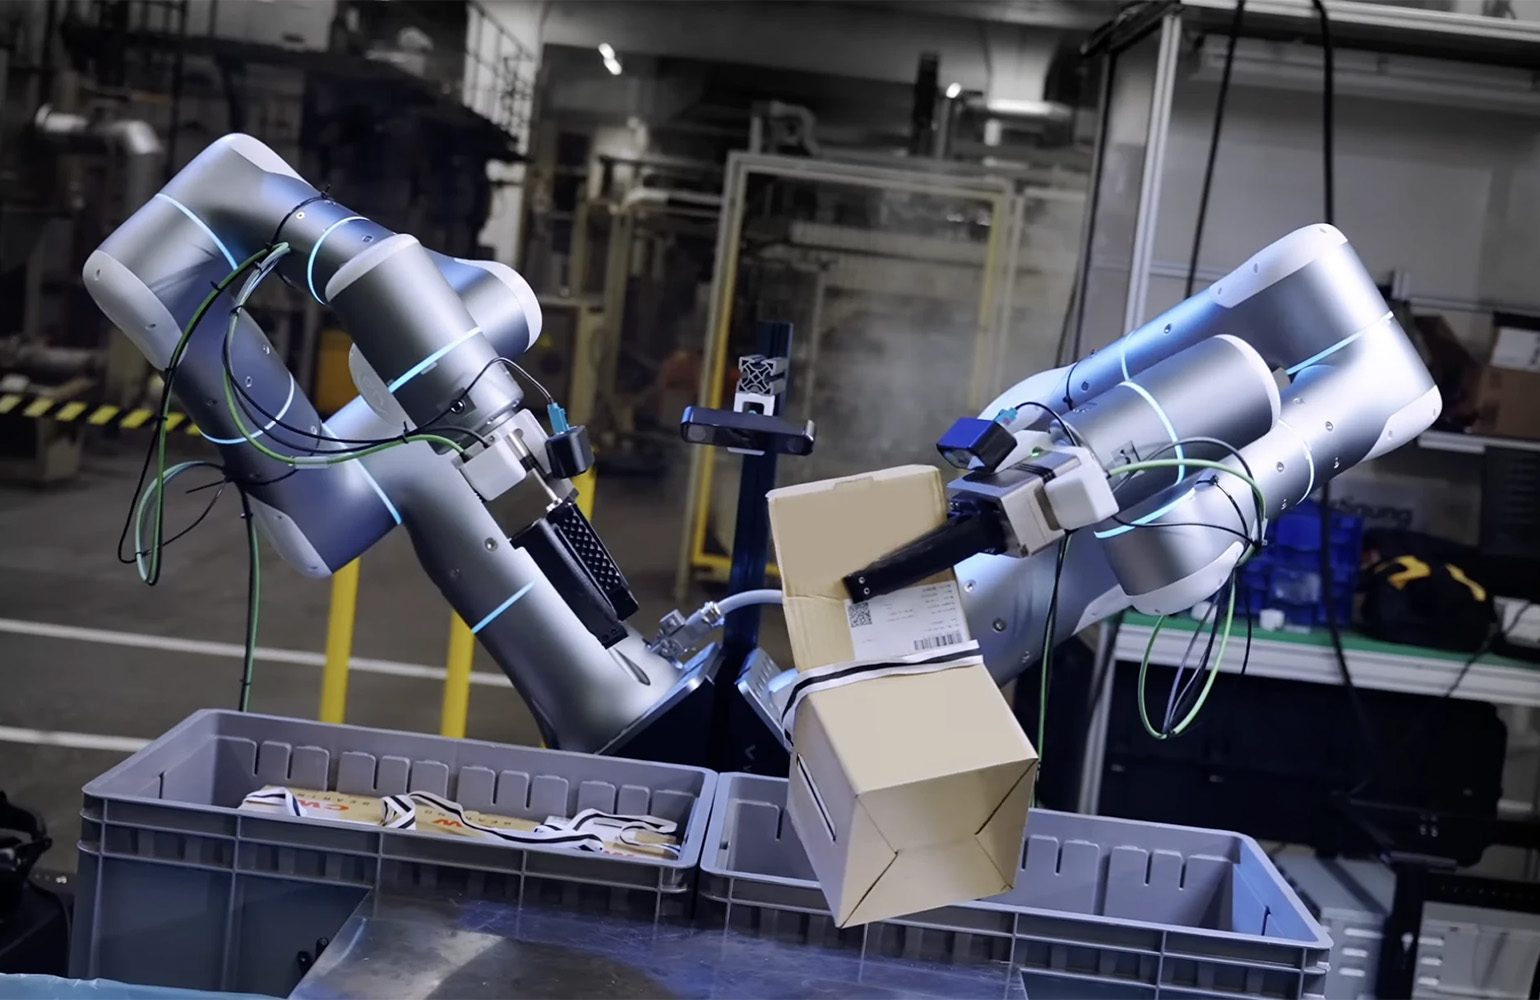
Robots shattered old limits in late 2026 by learning directly from over a million hours of human video—unlocking massive gains in accuracy, speed, and adaptability.
What to know
- Rhoda AI raised $450M and Dyna Robotics pretrained DYNA-2 on a staggering one million hours of first-person video, marking a new era of video-first robot training.
- World-action models now learn from massive egocentric human video to predict future actions, hitting 74.2% success on RoboTwin 2.0-Plus and 82.2% on LIBERO-Plus with little extra data.
- Systems like DreamZero and Xiaomi-Robotics-1 cut adaptation time to just 30 minutes and boosted benchmark success rates—DreamZero dropped validation loss by 24% and Xiaomi-Robotics-1 hit 57.6% on RoboCasa365, up from 46.6%.
Video Training Hits Scale
Million-hour video pretraining became feasible in 2026 as compute costs plummeted and web-scale data pipelines let robots learn from the internet’s vast troves of first-person footage.
The shift away from the teleoperation bottleneck became credible in 2026 because the inputs and infrastructure for video-first robot training suddenly looked scalable. The Robot Report captured the capital side in March with the headline “Rhoda AI exits stealth with $450M to train robots from video,” a sign that late-2026 robot programs expected training regimes far beyond hand-collected robot demos and had substantial resources to support million-hour-scale training, while IBM Technology explained why that ambition was newly practical: “compute efficiency… has gotten ridiculously good,” to the point that processing 20 million hours of video had fallen from years on older CPUs to weeks on current GPUs.
By late summer and early fall, the pipeline itself had come into focus: Gradient Flow described “a pre-training stage that's training on webcale data,” where teams “take pretty much any data any video data” and “use video generation as the modeling objective… predict what's going to happen in the future,” before a much shorter robot-specific post-training stage. That recipe fit the broader architecture shift described on Cognitive Revolution, where “the big breakthrough came in 2023” as Google trained a VLM to output robot actions directly, and the data source expanded to “the web,” with AI Engineer pointing to YouTube’s “five billion videos” and “millions of hours” of first-person human action footage.
Robots Predict, Not Memorize
World-action models now learn to forecast future events from video, enabling robots to generalize skills from a single example instead of rote repetition across hundreds of tasks.
The mechanism works because world-action models do not merely map images to motor commands; they first learn a predictive model of how the world changes, then attach action generation to that forecast. This is why a robot that watches one pouring example can generalize the concept instead of memorizing thousands of task-specific demonstrations, and why the evaluation can be done directly, without per-task fine-tuning, on 100 tasks across 20 manipulation skill groups with held-out scenes, backgrounds, lighting, and object instances.
That predictive prior becomes actionable when future-state modeling is coupled to action decoding, either jointly or through a lightweight inverse-dynamics stage, so systems learn mostly from video and only minimally from robot labels. The core mechanism is the use of massive egocentric human video datasets to pretrain world-action models that predict future video frames and robot actions, creating strong foundational priors that transfer efficiently to diverse robot embodiments and tasks with minimal additional data, with reported results including 74.2% success rate on RoboTwin 2.0-Plus and 82.2% on LIBERO-Plus.
Thresholds Unlock Rapid Transfer
Crossing the million-hour mark in egocentric video pretraining triggered a step-change in robots’ ability to adapt to new bodies and tasks in minutes, outpacing smaller-scale rivals.
The late-2026 break became visible on August 10, when Dyna Robotics said DYNA-2 had been pretrained on over one million hours of egocentric human video, “the equivalent of 170 years of continuous waking experience,” and that this scale revealed a “human-to-robot scaling law” with predictable gains on robotic tasks, according to Briefglance. Dyna also tied the break specifically to reaching roughly 1,000,000 hours, reporting a step-change in task success versus its own smaller-scale predecessor. That mattered not just as a bigger dataset, but as a threshold event: Briefglance placed DYNA-2 against a field still operating at smaller scales, with NVIDIA’s GR00T/EgoScale around 20,000 hours and Generalist AI’s GEN-1 at half a million, making the million-hour regime look like the differentiator.
What turned that scaling claim into a broader late-2026 pattern was the way it translated into adaptation speed and cross-embodiment transfer: Briefglance reported that the learned intuition could move to “different robot bodies… with just hours of fine-tuning,” including a case where robotic hands needed only 13 minutes of task-specific data to twist open a bottle cap. Dyna itself framed the result the same way in August, unveiling DYNA-2 as a model “trained on one million hours of first-person human video” that “Adapts to New Tasks in 13 Minutes,” and reporting a step-change in adaptation speed versus its own smaller-scale predecessor, tying the million-hour mark directly to a step-change in generalization and rapid task uptake.
Fine-Tuning Shrinks to Minutes
Video-pretrained robots slash adaptation time and outperform teleoperation-trained systems, with models like DreamZero and Xiaomi-Robotics-1 achieving record-breaking transfer and success rates on real-world tasks.
The clearest evidence of measured gains is head-to-head: Into AI reported that, “under fixed pretraining, post-training, and validation protocols, it also leads to superior performance,” with egocentric human video pretraining delivering 24% lower validation loss on real-robot action prediction, 52.5% higher in-distribution success, and 90% higher out-of-distribution success than teleoperated robot-data baselines. Into AI also found DreamZero beat prior VLA models on zero-shot generalization in unseen physical scenarios by more than 2× in task progress, showing that the newer video-pretrained stack was not just broader in scope but materially better on transfer.
The adaptation gap was just as striking: Into AI said DreamZero “works in real time and can quickly adapt to a new robot using about 30 minutes of play data,” while Not Boring described Praxis-1 reaching strong performance on some new-environment tasks with just minutes of data after robot-specific tuning. On benchmarked task success, Xiaomi-Robotics-1 pushed past earlier stacks with “a 57.6% success rate on RoboCasa365, surpassing the previous best of 46.6%,” and was “Trained on more than 100,000 hours of real-world manipulation trajectories collected across over 1,700 scenarios… intended to perform a wide range of mobile manipulation tasks while adapting efficiently to new” settings.