AI's new bottleneck: why memory, not compute, is now the real cost killer
The gist
The AI race is hitting a new bottleneck—memory, not compute, is now the true cost killer reshaping everything from system design to business strategy.
What to know
- A single GPT-3 session at 2,048 tokens eats up 10 GB of KV cache, limiting even top GPUs like Nvidia's GB200 to just 40 concurrent users.
- Breakthroughs like Grouped-Query Attention, Dynamic Memory Sparsification, and Meta's STEM are cutting memory requirements and compute by up to 8x, but memory scaling laws still cap AI concurrency and economics.
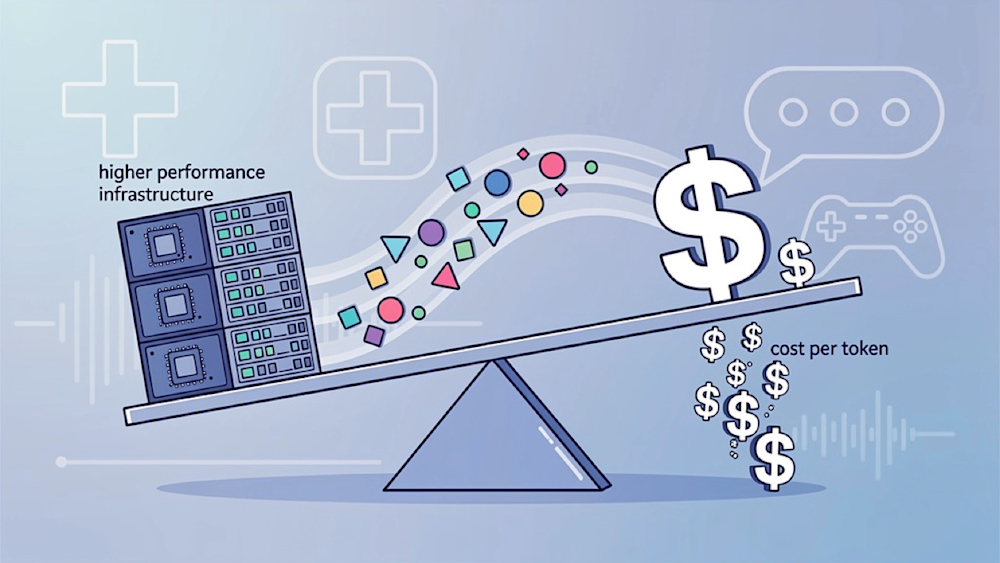
- Open-source models and optimized infrastructure are slashing AI deployment costs by as much as 90%, pushing enterprises to rethink cloud vs. on-prem strategies for cheaper, more resilient AI.
Memory Becomes the Battlefield
AI infrastructure has shifted from compute-focused to memory-centric, with KV cache scaling laws now capping concurrency and driving a wave of multidisciplinary innovation in both hardware and software.
Over the past several years, the AI infrastructure landscape has undergone a dramatic shift: memory bandwidth, latency, and reliability have overtaken raw compute as the primary bottlenecks shaping both the feasibility and economics of large-scale AI deployments. As Tim Dettmers observed, practitioners now weigh memory constraints more heavily than compute when reasoning about what’s possible, and Sebastian Borgeaud of Gemini 3 underscored that the era of isolated model-building has given way to a multidisciplinary systems approach—where optimizing memory and bandwidth across data, models, and infrastructure is now the central challenge.
By early 2026, the KV cache—responsible for storing the model’s running state during inference—has emerged as the dominant scaling and cost challenge, eclipsing even the storage of model weights. For instance, a single GPT-3 session at 2,048 tokens can consume 10 GB of KV cache, meaning a top-tier NVIDIA GB200 tray with 744 GB HBM3e can support only about 40 concurrent users. This linear growth in KV cache with context length directly limits user concurrency and drives up infrastructure costs, fundamentally altering the economics of AI inference and prompting a wave of innovation in both hardware and software.
To address these memory bottlenecks, the industry has responded with a flurry of architectural and algorithmic innovations. Techniques like Grouped-Query Attention and Multi-Head Latent Attention have slashed KV cache size per token from 4.5 MB to as little as 71 KB, while hybrid architectures reduce the number of attention layers requiring KV storage. However, even these advances only partially alleviate the problem, as the fundamental scaling laws of KV cache—dictated by context length, layer count, and attention head configuration—continue to impose a fixed 'bytes-per-token' tax that constrains batching and concurrency.
The hardware response has been equally ambitious, with NVIDIA’s Context Memory Storage Platform and Cerebras’s MemoryX leading the charge to decouple compute from memory. These solutions tier memory across HBM, DRAM, and NVMe, enabling petabyte-scale context storage and fast, persistent KV cache access beyond the GPU—critical for supporting trillion-token workloads and high-concurrency agentic LLMs. Yet, as Val Bercovici notes, this new 'context memory storage' market brings its own economic complexities, from tiered pricing models to the need for sophisticated management of both logical and physical KV caches.
At the hardware-software interface, the decode phase of inference—where output tokens are generated one at a time—has become almost entirely memory-bandwidth bound, leaving the majority of GPU compute units idle. The roofline model starkly illustrates this mismatch: while chips like NVIDIA’s H100 boast theoretical FP16 compute in the thousands of TFLOPS, their memory bandwidth is the true limiter, with arithmetic intensity during decode often falling below 4 FLOPs per byte—orders of magnitude below what’s needed to fully utilize the silicon. As a result, further scaling of compute alone cannot resolve these bottlenecks, making memory bandwidth and KV cache management the new frontiers of AI infrastructure optimization.

Orchestrating Memory at Scale
Innovative memory management, from compaction to tiered caching, is transforming AI economics as surging DRAM prices and multi-agent workloads make memory orchestration a business-critical differentiator.
The relentless growth in AI agent workloads has driven a wave of innovation in memory management, with companies like OpenAI pioneering advanced orchestration techniques. Their Server-side Compaction, introduced in early 2026, enables agents to summarize and retain only the most essential context across sessions involving millions of tokens, ensuring both scalability and efficiency. This is complemented by the new Skills framework, which allows agents to modularize and persist procedural knowledge, supporting sophisticated, long-running workflows without overwhelming memory resources.
As large language models stretch their context windows to unprecedented lengths, memory and caching strategies have evolved to keep pace. Nvidia’s Dynamic Memory Sparsification (DMS), unveiled in February 2026, exemplifies this trend by compressing the key-value cache and reducing memory costs for reasoning tasks by up to 8x, all without sacrificing accuracy. DMS’s intelligent token eviction and delayed removal mechanisms not only boost throughput—up to 5x on enterprise hardware—but also integrate seamlessly with existing Hugging Face pipelines, sidestepping the need for custom hardware or retraining.
The explosion of multi-agent, high-concurrency workloads has transformed the KV cache market, pushing storage beyond traditional HBM and DRAM onto NVMe tiers and spawning new economic models. As Val Bercovici observes, AI startups now routinely consume trillions of tokens daily, driving demand for tiered cache write durations and complex pricing strategies, such as Anthropic’s 5-minute and 1-hour cache tiers. This shift has made cache management not just a technical challenge but a business-critical lever, with prompt caching and memory orchestration now determining whether companies can stay afloat amid soaring DRAM prices—up sevenfold in the past year.
Scaling LLM deployments to handle million-token contexts has exposed the limits of traditional memory architectures, necessitating distributed and tiered solutions. Techniques like Context Parallelism and Ring Attention partition sequences across multiple GPUs, overlapping communication and computation to avoid the bandwidth cliffs of Tensor Parallelism—where NVLink’s 900 GB/s plummets to just 50 GB/s over InfiniBand. With a 70B model requiring 328 GB of KV cache for a million-token context, only distributed memory orchestration and innovative cache compression, such as DeepSeek-V2’s Multi-head Latent Attention, can make such deployments feasible and cost-effective.


Architectural Breakthroughs Redefine Scale
New model designs—like sparse transformers, STEM, and State Space Models—are slashing both compute and memory costs, finally breaking the quadratic scaling barrier that once stifled large-context AI.
By early 2026, architectural innovations such as Meta's STEM method and the rise of sparse transformer architectures have dramatically shifted the efficiency landscape for large language models. Meta's STEM replaces the traditional up-projection in transformer feedforward networks with a token-indexed embedding lookup, slashing compute requirements by about one-third while actually boosting accuracy on challenging reasoning benchmarks like MMLU and GSM8K. In parallel, the adoption of sparse transformer designs—most notably Mixture of Experts (MoE) models as seen in the LLaMA-4 family—enables conditional computation by activating only a small subset of parameters per token, yielding a roughly 3× reduction in FLOPs per token compared to dense models. Together, these advances mark a decisive move away from brute-force scaling toward smarter, more targeted use of computational resources.
The pursuit of long-context and agentic AI has spurred a wave of efficiency breakthroughs at both the architectural and inference levels. Techniques like adaptive token-level layer skipping dynamically tailor computation to token complexity, skipping transformer layers for simpler inputs and even improving model performance by bypassing noisy layers—demonstrated by models achieving better results when skipping an average of four out of 32 layers. Meanwhile, Direct Multiple Token Decoding (MTD) repurposes idle transformer layers to predict multiple tokens in parallel, doubling inference speed for large models with minimal accuracy loss. These methods not only align computational effort with task difficulty but also enable rapid integration with pretrained models, signaling a new era of flexible, scalable AI deployment.
A fundamental architectural shift is underway with the emergence of State Space Models (SSMs) and Mamba, which challenge the transformer’s reliance on quadratic memory growth for long-context processing. Unlike traditional attention mechanisms that require storing every token’s key and value—leading to ballooning memory costs—SSMs compress the entire past sequence into a fixed-size mathematical state, updated via control theory-inspired differential equations. As one analysis puts it, 'the KV cache drops to exactly zero,' enabling O(1) memory usage during generation regardless of whether the context is 100 or 1,000,000 tokens long. This breakthrough not only eliminates the quadratic 'tax' but also paves the way for truly scalable, persistent-memory AI agents.
Linear Attention techniques offer another promising avenue for scaling transformer models efficiently, circumventing the quadratic complexity imposed by the Softmax function in standard attention. By leveraging kernel factorization and associative matrix multiplication, Linear Attention reduces the intermediate computation from an (n × n) attention map to a much smaller (d × d) matrix, drastically lowering both memory and compute requirements. However, this mathematical sleight of hand comes with precision tradeoffs, as the removal of Softmax can impact the fidelity of attention distributions—highlighting the ongoing balancing act between efficiency and accuracy in next-generation AI infrastructure.
System Integration Drives Efficiency
The real leap in AI scalability comes from tightly integrated hardware, software, and power systems, not just faster chips, as next-gen data centers unite GPUs, memory platforms, and DC-native power to support surging AI demands.
The evolution of AI infrastructure is increasingly defined by holistic system integration, where next-generation hardware like Nvidia's Blackwell GPUs and BlueField-4 DPUs are paired with advanced software stacks and innovative data center power architectures. While early 2026 hardware advances, such as Nvidia's, have delivered notable—though not exponential—compute efficiency gains (roughly 2x rather than 3x or 4x), the real breakthroughs come from system-level design that optimizes power usage and operational costs. This shift in focus underscores that the path to supporting demanding AI workloads and slashing inference costs lies not in raw compute alone, but in the seamless interplay between hardware, software, and infrastructure.
NVIDIA’s Context Memory Storage Platform exemplifies this integration, leveraging BlueField-4 DPUs and software solutions like WEKA’s Augmented Memory Grid to address memory bottlenecks that have long constrained AI inference. By enabling KV cache to move efficiently and directly between GPU HBM and petabyte-scale NVMe storage—with minimal overhead—these systems unlock new levels of scalability and throughput for large-scale AI workloads. As the platform connects GPU clusters such as GB200 to vast storage pools via technologies like NVIDIA Dynamo and NIXL, it demonstrates how tightly coupled hardware-software architectures are now essential to supporting the next wave of AI applications.
The drive for efficiency extends beyond compute and memory to the very foundations of data center infrastructure, as seen in the adoption of 800VDC power architectures. Enteligent’s 2026 white paper highlights that these systems can reduce copper usage by up to 80% and deliver millions in capital and operational savings for every 10 MW deployed, directly supporting the higher rack power densities demanded by modern AI. As legacy AC systems struggle to keep up, the industry is aligning around DC-native designs—often through collaborative efforts like the Open Compute Project—to ensure that power delivery keeps pace with the surging requirements of AI hardware and workloads.
Ultimately, the most dramatic reductions in AI inference costs—up to 10x, according to Nvidia’s own analysis—are only possible when next-generation hardware is combined with optimized software stacks, open-source models, and infrastructure investments. Hardware alone delivers about a 2x gain, but true cost breakthroughs require innovations like low-precision formats (NVFP4), mixture-of-experts architectures, and continuous batching techniques in inference engines such as vLLM. As Dion Harris of Nvidia puts it, 'Performance is what drives down the cost of inference... throughput literally translates into real dollar value,' making holistic system design the linchpin for both efficiency and scalability in AI data centers.
Efficiency Reshapes AI Business Models
Cost-slashing innovations and open-source models are forcing enterprises to rethink cloud vs. on-prem strategies and enabling the rise of persistent, business-tailored AI agents that embed institutional knowledge at scale.
Efficiency and cost reduction have rapidly become the defining battlegrounds in AI infrastructure, fundamentally altering business models and procurement strategies across the industry. As former Facebook Chief Privacy Officer Chris Kelly observed, 'finding efficiency is going to be one of the key things that the big AI players look to,' with companies able to lower data center costs poised to dominate. This trend is further accelerated by the rise of open-source AI models—particularly from Chinese firms like DeepSeek, whose sub-$6 million large language model launch in late 2024 dramatically undercut U.S. competitors—broadening access and forcing established players to rethink their procurement and deployment approaches.
The relentless drive for efficiency is reshaping the economics of AI deployment, with innovations like Meta’s Avocado and Nvidia’s Blackwell GPUs slashing inference costs by up to 10x and reducing energy use, thereby enabling enterprises to scale AI applications to millions of users at a fraction of previous costs. Companies such as Sully.ai have reported 90% reductions in healthcare AI inference expenses and 65% faster response times by switching to open-source models on optimized hardware, while production data from Baseten, DeepInfra, Fireworks AI, and Together AI shows similar cost-per-token drops across sectors. This new landscape forces businesses to weigh cloud versus on-premises deployments more carefully, as high-throughput infrastructure investments and memory bandwidth optimizations—not just raw compute—now drive procurement decisions and bottom-line impact.
The evolving AI infrastructure landscape is also fueling the rise of persistent, context-aware AI agents, as efficiency gains and architectural innovations make it feasible to deploy advanced, memory-rich systems at scale. With AWS’s new 'Stateful Runtime Environment' for OpenAI agents and Cloudera’s on-premises Blackwell-powered offerings, enterprises can now choose between stateless and stateful AI services, aligning infrastructure with complex business workflows that demand long-term context and identity retention. This marks a decisive shift away from one-size-fits-all procurement toward specialized, firm-customized platforms that embed institutional knowledge and social norms, enabling near-perfect accuracy and reliability for business-critical applications.
Despite the promise of these innovations, the business impact of AI infrastructure remains a high-stakes gamble: only 32% of organizations report positive ROI from AI projects, yet the majority continue to pour budgets into data, storage, and compute. The complexity and cost of data storage—alongside mounting security concerns, with 44% of firms suffering cloud data loss and 41% lacking adequate vendor security tools—are driving a surge in hybrid cloud and on-premises solutions, as 64% of organizations now opt for hybrid storage to balance flexibility, compliance, and cost control. This underscores a strategic shift in procurement, with businesses seeking infrastructure that can deliver both operational resilience and economic predictability in an increasingly volatile landscape.