Modal hits decacorn status as AI infra goes elastic
The gist
Modal just hit decacorn status by turning the AI GPU scramble into a $16B business built on elastic, programmable infrastructure.
What to know
- Inference demand now dominates AI compute, with Deloitte projecting it will jump from one-third in 2023 to two-thirds by 2026.
- Modal pools GPU supply across 25 clouds, letting customers rent scalable AI inference power instead of hoarding hardware.
- Despite Modal's $1B+ ARR and $16B valuation, skeptics warn soaring power needs, scarce data center space, and rising GPU rental prices could limit growth.
Idle GPUs Become Costly Liability
As inference workloads surge, AI operators are racing to keep GPUs fully utilized, driving a shift from static clusters to dynamic, usage-based orchestration that slashes waste and cuts costs per output.
The market shifted because AI infrastructure stopped being a race to install GPUs and became a race to keep them productive under inference-heavy demand. Since 2024, providers had competed to put more GPUs on the floor, but now keeping them busy is the different problem, and Hyperbolic argues that idle capacity is the most expensive problem in this market. That logic pushed operators to aggregate fragmented capacity and dynamically tune storage, networking, tenancy, and routing around latency and cost-per-output instead of relying on fixed clusters. QumulusAI said it signed more than $124 million in three-year AI infrastructure agreements tied to Nvidia Blackwell deployments, with contracts centered on inference workloads.
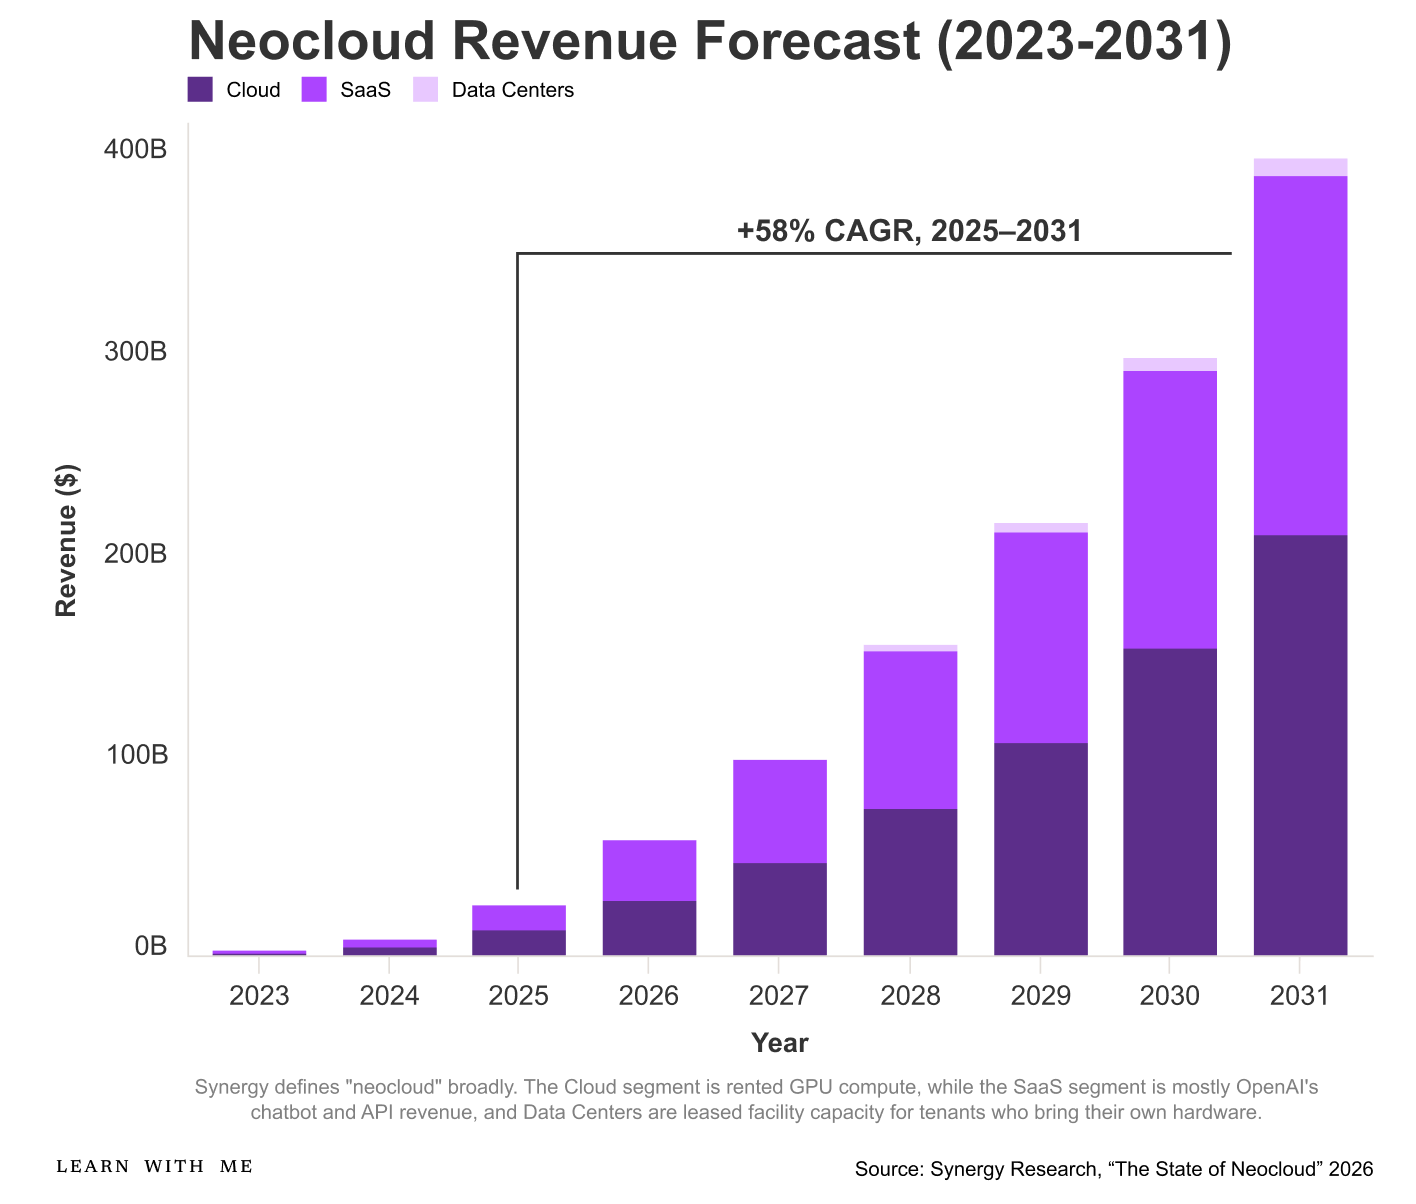
That orchestration layer became necessary as inference overtook training in both scale and volatility. Forbes says that in 2023, inference drove one-third of AI compute, and by 2026 Deloitte projects it will be two-thirds, while inference is growing at a 79% CAGR compared to 25% for training. Teams that planned infrastructure like a training run were left with clusters that could not handle real demand, so the answer became usage-based, elastic compute shaped by workload data and custom optimizations. NVIDIA Developer reports FP8 post-training quantization with NVIDIA Model Optimizer cut Llama-3.1-8B weight memory by 43.5% without retraining, and one provider cited a customer paying less than $3 per million token.
Software Unifies Global GPU Fleets
Modal’s deep abstraction layer transforms scattered GPUs from 25+ clouds into a seamless, programmable pool, unlocking elastic inference at scale with advanced scheduling and rapid data movement.
The core of the model is not owning a giant monolithic cluster, but turning scattered GPU supply into one programmable pool. As Hyperbolic explained on 2026-10-18, its “Forge” acts as “a unified control plan” where “you can take any bare metal cluster across the world, attach it to our control plan” and virtualize it for multi-tenant use; Modal applies the same logic at broader scale, with its CEO saying, “We work with 25 different clouds at this point and adding more all the time,” so customers consume capacity as a service rather than sourcing hardware themselves.
That abstraction only works because the software layer is unusually deep: Hyperbolic described “a global scheduler” that lets a user request H100 nodes and automatically finds matching resources across the fleet, while Modal rebuilt the stack for bursty inference with its own scheduler, autoscaler, file system, and snapshotting. On Unsupervised Learning, Modal said that over “the last six months” it built “an incredibly complex system that basically uses RDMA over peer to peer between the nodes to copy data very fast,” alongside “disaggregated pre fill,” KV caching, and efficient kernels, so large models can be loaded, moved, and scaled up or down fast enough to make inference feel elastic.

Modal's Leap to Infra Giant
Modal’s $750M Series D and decacorn status signal its transformation from developer tool to dominant AI infrastructure platform, with investors betting on its ability to deliver massive, flexible compute at scale.
By October 2026, the market was no longer treating Modal as an interesting developer tool but as a scaled infrastructure company with decacorn stature. Latent.Space made that explicit in its headline, “Modal Becomes NYC AI Infra Decacorn Amid Explosive Sandbox Growth,” while The Next Web tied the company’s late-stage financing directly to operating momentum, saying “Modal’s Erik Bernhardsson taps Nvidia Vera CPU, doubling throughput as $750 M Series D fuels growth,” a framing that connected capital, performance gains, and category-scale demand.
Those signals matter because they show valuation and revenue expectations rising together, not in isolation: a $750 million Series D and a headline emphasis on “doubling throughput” suggested investors were backing a business already serving workloads at meaningful scale. The Next Web’s focus on Erik Bernhardsson’s infrastructure choices underscored that Modal was behaving like a company optimizing a large, fast-growing platform, and that combination of decacorn status, roughly $1 billion in annual recurring revenue, and a $16 billion valuation marked flexible AI infrastructure as a major market category by late 2026.
Physical Limits Strain AI Growth
Despite software advances, power, data center space, and hardware shortages are driving up GPU rental prices and shifting risk, exposing the hard limits that could curb AI infrastructure expansion.
Skeptics say software abstraction cannot wish away physical bottlenecks. As Chamath Palihapitiya put it, “packing those GPUs together also raises rack power from roughly 10 to 15 kilowatts to 40 to 250 kilowatts, which requires new networking, electrical systems, and often liquid cooling,” while another 2026 analysis warned builders still “cannot find the land, they cannot find the premise, they cannot find electrical power,” and even turbines and transformers were sold out for years—evidence that power, space, and grid hardware, not orchestration alone, can cap supply and keep costs elevated. That same discussion also turns on financing: “Who carries the risk and how is the cluster financed?”
The pricing data also gives skeptics ammunition: in AI Infrastructure Growth Faces Market and Supply Constraints, “B200 prices were 8% lower 36 months out… H100 is 13% lower and A100 is 15% lower,” but “over the subsequent three to six months, we see the entire curve essentially moved upward,” meaning renters had to pay more per GPU hour across terms. The speaker contrasts earlier depreciation assumptions with current contract behavior—“back of the m napkin math… first three years the price is held constant… then year four five and six each year you are roughly”—while Supply Chain, Data Center Strategy, and New Economics for AI Chips adds that “finding data centers is obviously harder and harder,” and cites an NVL72 first lined up at $3.5 million before “we sold it to someone else for 5 million.” That contract structure can shift risk rather than remove it, as shown by CoreWeave, where “98% of their revenue came from committed contracts in 2025.”